
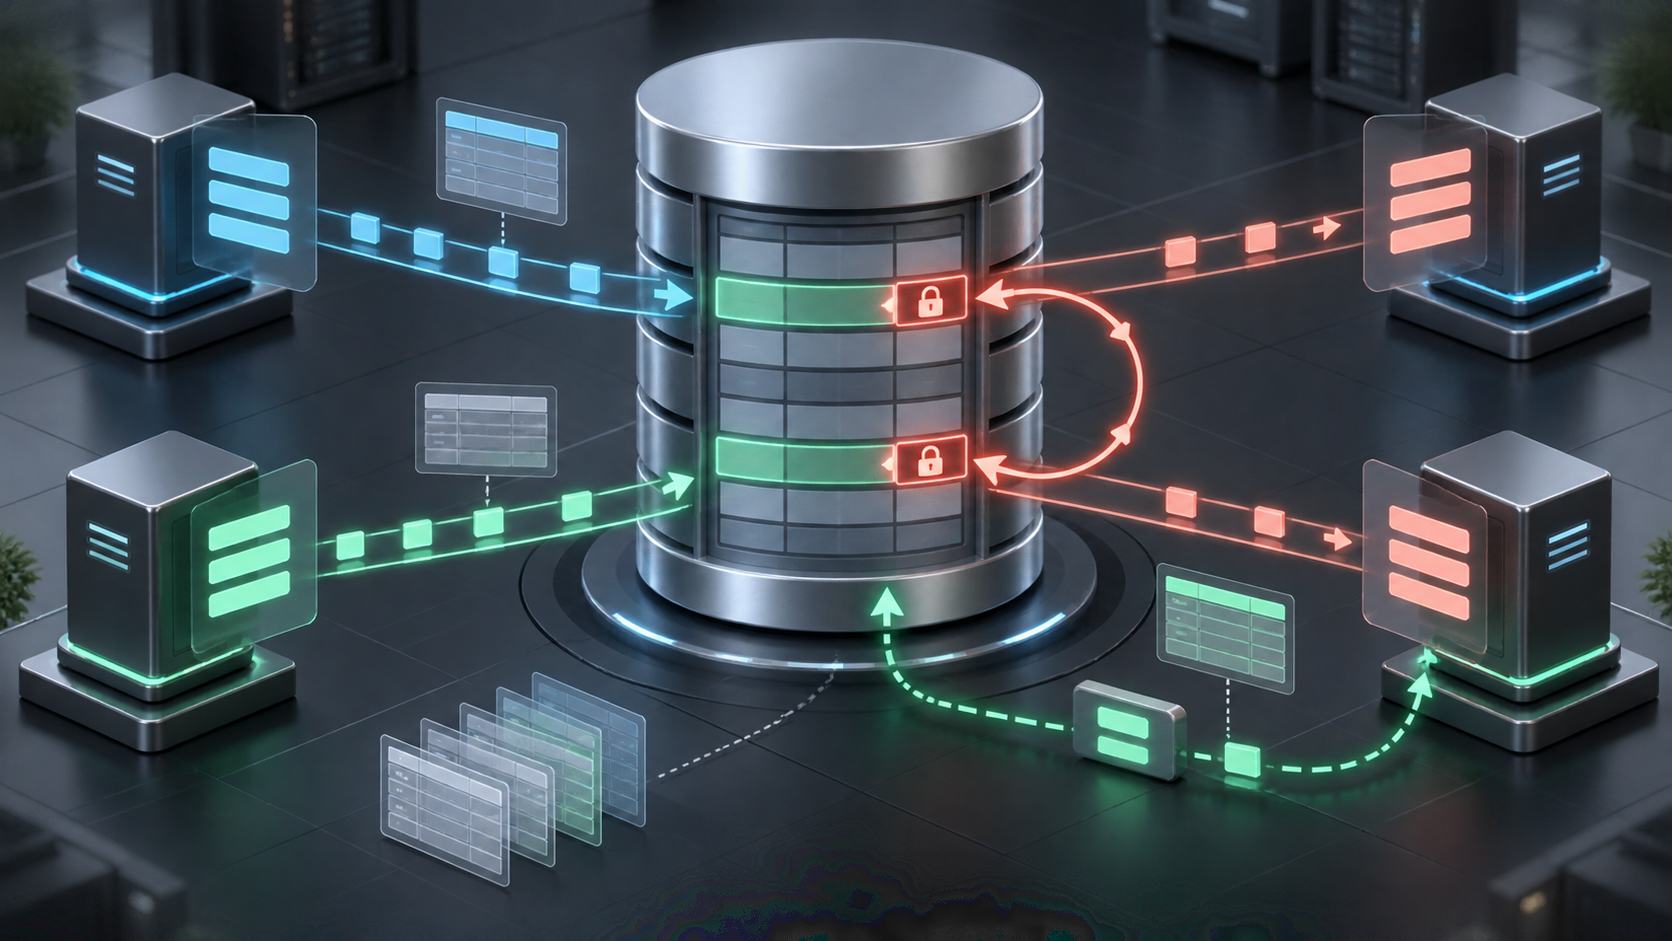
An order that crosses payment, inventory, and shipping services cannot be protected by one database transaction. Each service owns separate data and may slow down or become unavailable at any point. If payment authorization succeeds but inventory reservation fails, the backend must know which steps completed, what must be compensated, and how to resume after a process restart. The Saga Pattern addresses this class of workflow as a sequence of local transactions with deliberate compensating actions.
This guide moves from applicability boundaries to production design: distinguish a saga from ACID transactions and the Transactional Outbox, model a state machine, select choreography or orchestration, define business compensations, tolerate duplicate and out-of-order messages, set timeouts and retries, add observability, and test failure paths. The goal is not to imitate a perfect global transaction. It is to make intermediate states, failures, and recovery explicit and controllable.
1. Why is a local transaction insufficient?
In a monolith with a shared database, creating an order, reducing stock, and recording payment may fit in one transaction. The database guarantees that every change commits or every change rolls back. Once these capabilities move into separate services and data stores, the order service transaction cannot roll back a change already committed by the payment service.
Holding a distributed transaction such as two-phase commit across every dependency increases coupling, can retain locks for a long time, and requires all participants to support the protocol. That is impractical for many microservice systems and third-party integrations. A saga chooses a different contract: each step commits locally; if a later step fails, the workflow executes business operations that compensate for earlier steps.
| Mechanism | Guarantee scope | Key point |
|---|---|---|
| Database transaction | One database or resource manager | Technical rollback before commit |
| Transactional Outbox | Data and an event intent written in one transaction | Does not coordinate a multi-step workflow by itself |
| Saga | A sequence of local transactions across participants | Recovery uses compensations and workflow state |
A saga does not create instantaneous atomicity across the system. It creates an eventually consistent process with a designed success path and recovery path.
2. Begin with invariants and business boundaries
Before drawing message arrows, write the invariants. An order may be confirmed only after both payment and stock are reserved; a coupon must not be redeemed twice; a refund must not exceed the captured amount. Then identify which aggregate owns each decision and when intermediate state may be visible to a user.
Not every flow across two services needs a saga. A fan-out read is not a transaction. Work that can live entirely inside one service should not be fragmented simply to apply a pattern. A saga fits a workflow that contains multiple local transactions, lasts longer than an ordinary request, must continue through transient faults, and has meaningful business actions for moving forward or compensating.
- Name states precisely, such as
PAYMENT_PENDING,STOCK_RESERVED,CONFIRMED,COMPENSATING, andCANCELLED. - Identify terminal, retryable, and manual-intervention states.
- Define who owns the overall deadline and who is authorized to cancel the workflow.
- Avoid vague terms such as “processed” when participants interpret them differently.
3. Design an order saga
An order saga might create a pending order, authorize payment, reserve inventory, request shipment, and confirm the order. Every step changes participant-owned data in a local transaction. An event or command should be published reliably only after that commit, commonly through a Transactional Outbox.
START
  -> CreateOrder
  -> AuthorizePayment
  -> ReserveInventory
  -> RequestShipment
  -> ConfirmOrder
  -> COMPLETED

on ReserveInventoryFailed:
  -> ReleasePaymentAuthorization
  -> CancelOrder
  -> COMPENSATED
This is a business flow, not a promise that each step runs exactly once. A broker may redeliver; a consumer may commit and crash before acknowledgement; a response may arrive after a timeout. The design must tolerate at-least-once delivery with idempotency and must treat each transition as a conditional state change.
4. Choreography: participants react to events
In choreography, no central process commands every step. Order Service publishes OrderCreated; Payment Service reacts and emits PaymentAuthorized; Inventory Service reacts and emits its result. This reduces direct dependency on an orchestrator and can work well for a short, linear workflow with few participants.
The cost appears as the flow grows. Coordination logic becomes distributed across consumers, the overall path is harder to see, event loops can develop, and reordering steps may require changes in several services. To prevent “event soup,” every event should express a fact that has occurred with a clear schema and owner. Do not disguise commands behind generic event names such as ProcessNext.
- Prefer choreography when the chain is short and each reaction has natural domain meaning.
- Carry correlation ID and saga ID through every message.
- Record which participant emitted an event and which contract version it used.
- Set boundaries so one event cannot accidentally trigger an unpredictable network of work.
5. Orchestration: a state machine controls the workflow
In orchestration, a Saga Orchestrator persists state and sends commands to participants. It receives replies, validates transitions, and selects the next forward or compensating step. The orchestrator should not own internal payment or inventory rules. It owns process logic: which step runs, when a transition is valid, and how the workflow reacts to expiry.
Orchestration makes a complex flow easier to observe and change, but introduces an important component that must be durable. Workflow state must be persisted before or atomically with the intent to send a message; it cannot exist only in memory. Multiple orchestrator instances need safe work claiming through conditional updates, queue partitioning, or optimistic locking.
transition(sagaId, expectedState, reply):
  begin transaction
    saga = load sagaId
    if saga.state != expectedState: return DUPLICATE_OR_STALE
    next = decide(saga, reply)
    update saga set state = next.state, version = version + 1
    insert outbox(next.command)
  commit
This transaction prevents the new state and the next command from being split. The outbox relay can still publish the command more than once, so participants remain idempotent. The orchestrator should also store transition history or audit events so operators can understand why a saga reached its current state.
6. Compensation is not a technical rollback
After a local transaction commits, its data and external effects may already be visible. Compensation is a new business action that neutralizes an effect; it does not turn back time. Voiding a payment authorization differs from refunding a captured payment. Releasing a reservation differs from blindly increasing stock. An apology email cannot retract a confirmation already delivered to an inbox.
| Forward step | Possible compensation | Risk to handle |
|---|---|---|
| Authorize payment | Void or release authorization | Authorization may have expired or been captured |
| Reserve inventory | Release the exact reservation ID | Duplicate messages must not add stock twice |
| Create shipment | Cancel shipment request | Parcel may already have been handed to the carrier |
| Apply coupon | Restore redemption according to policy | Coupon may have expired while the saga ran |
Every compensation needs an idempotency key, a state precondition, and explicit outcomes: compensated, no compensation required, transient failure, or cannot compensate automatically. For irreversible effects, the workflow needs a pivot point. Before the pivot it may cancel; after the pivot it must move forward or enter a human exception process.
7. Idempotency, ordering, and late messages
Business exactly-once behavior cannot rely on the broker alone. A participant should persist a message_id or idempotency_key and the processing result in the same local transaction. On redelivery, the consumer returns the previous result or safely ignores the message. The idempotency scope must include the operation and resource, not merely the endpoint.
Out-of-order messages must be constrained by state and version. A PaymentAuthorized reply arriving after cancellation cannot confirm the order. The orchestrator can recognize a stale reply through saga_id, step_id, expected state, and attempt. If the participant already performed a late effect, the workflow may need an additional compensation rather than simply discarding the reply.
if inbox.contains(message.id):
    return inbox.previousResult(message.id)

if order.state != "PAYMENT_PENDING":
    return STALE_TRANSITION

applyPaymentResult()
inbox.record(message.id, result)
outbox.add(nextEvent)
commit()
8. Timeouts, retries, and the overall deadline
A timeout does not prove that a step failed. It proves only that the caller did not receive a result in time. Therefore, do not compensate blindly. The orchestrator can first query status by operation ID or resend the command with the same idempotency key. A participant should distinguish request not seen, in progress, succeeded, and definitively failed.
Retries should use exponential backoff, jitter, and an attempt limit. Validation failures and business rejections should not be retried like network faults. Each step has a timeout, but the saga also needs an overall deadline so it cannot remain pending forever. After the deadline, the state machine moves to compensation or manual intervention according to reversibility.
- Persist
next_attempt_atinstead of holding a waiting thread. - Do not use retries to hide a long dependency outage; combine them with a circuit breaker and concurrency limits.
- Send poison messages to a dead-letter queue with diagnostic context, but do not treat DLQ placement as successful compensation.
- Separate retries for forward steps from compensation retries because their operational priority differs.
9. Data model, schemas, and evolution
A minimal saga record commonly contains saga_id, workflow type, business key, state, version, deadline, current step, attempt count, and timestamps. Large payloads should not be copied indefinitely through messages. Store a stable reference and snapshot only the data required for decisions or compensation.
A workflow can outlive a deployment, so new code must understand sagas created by an older version. Persist a workflow_version, version message schemas, and retain compatible handlers while old instances remain. Do not change the meaning of an existing state in place. For a large migration, allow old workflows to drain or build an auditable state-upgrade transition.
10. Observability and operational controls
A dashboard that counts only successful messages is insufficient. Track saga count by state, age of the oldest pending saga, step latency, retry rate, compensation rate, permanent failures, and outbox lag. Structured logs should carry saga_id, business key, step, attempt, message ID, and trace ID while excluding payment data and other sensitive information.
Operators need a timeline viewer and controlled actions to retry a step, trigger a reviewed compensation, or mark a case for manual handling. A “rerun everything” button is dangerous because it can repeat effects that already succeeded. Administrative operations need authorization, audit logs, and the same idempotency guarantees as the automated path.
A saga without state visibility, stuck-workflow alerts, and a recovery runbook is not production-ready even when its happy path works.
11. Test a failure matrix, not just the happy path
Participant unit tests are necessary but insufficient. Integration tests should inject faults before commit, after commit but before acknowledgement, during outbox publication, on duplicate replies, and on late replies. At every failure point, assert the final state, the number of business effects, and the ability to continue after an orchestrator restart.
| Test scenario | Expected result |
|---|---|
| A command is delivered twice | One business effect and a stable result |
| Participant commits but loses its response | Retry with the same key does not repeat the effect |
| The third step rejects the business operation | Steps two and one are compensated in a valid order |
| Orchestrator crashes during a transition | Restart continues from durable state |
| Compensation has a transient failure | Independent retry; saga is not reported fully cancelled |
| An old reply arrives after cancellation | Workflow is not revived; extra compensation runs if required |
Use a fake clock for deterministic timeout and backoff tests instead of random sleeps. Contract tests protect message schemas between producers and consumers. Finally, exercise the system in an environment close to production with the actual broker, database, and partition strategy because many race conditions do not appear in in-memory tests.
Production checklist
- Invariants, states, and the owner of every decision are explicit.
- Every step is a local transaction; state and outbox intent commit atomically.
- Commands, replies, forward steps, and compensations are idempotent.
- A timeout is treated as an unknown outcome, not automatic failure.
- Compensations reflect real business behavior and have a path for irreversible effects.
- The saga has a deadline, retry budget, dead-letter policy, and manual-intervention state.
- Messages carry saga ID, step ID, schema version, and correlation context.
- Dashboards, stuck-workflow alerts, timelines, and audited operational controls are ready.
- The failure matrix covers duplicates, crashes, timeouts, reordering, and compensation failures.
The Saga Pattern is useful when process consistency must cross service boundaries without a global transaction. A sound design does not conceal intermediate state. It models a clear state machine, commits message intent through an outbox, tolerates redelivery with idempotency, and treats compensation as first-class domain behavior. When deadlines, observability, operational tools, and failure tests are built alongside the happy path, a distributed workflow can recover predictably in production.


No comments yet. Be the first to share your thoughts.