
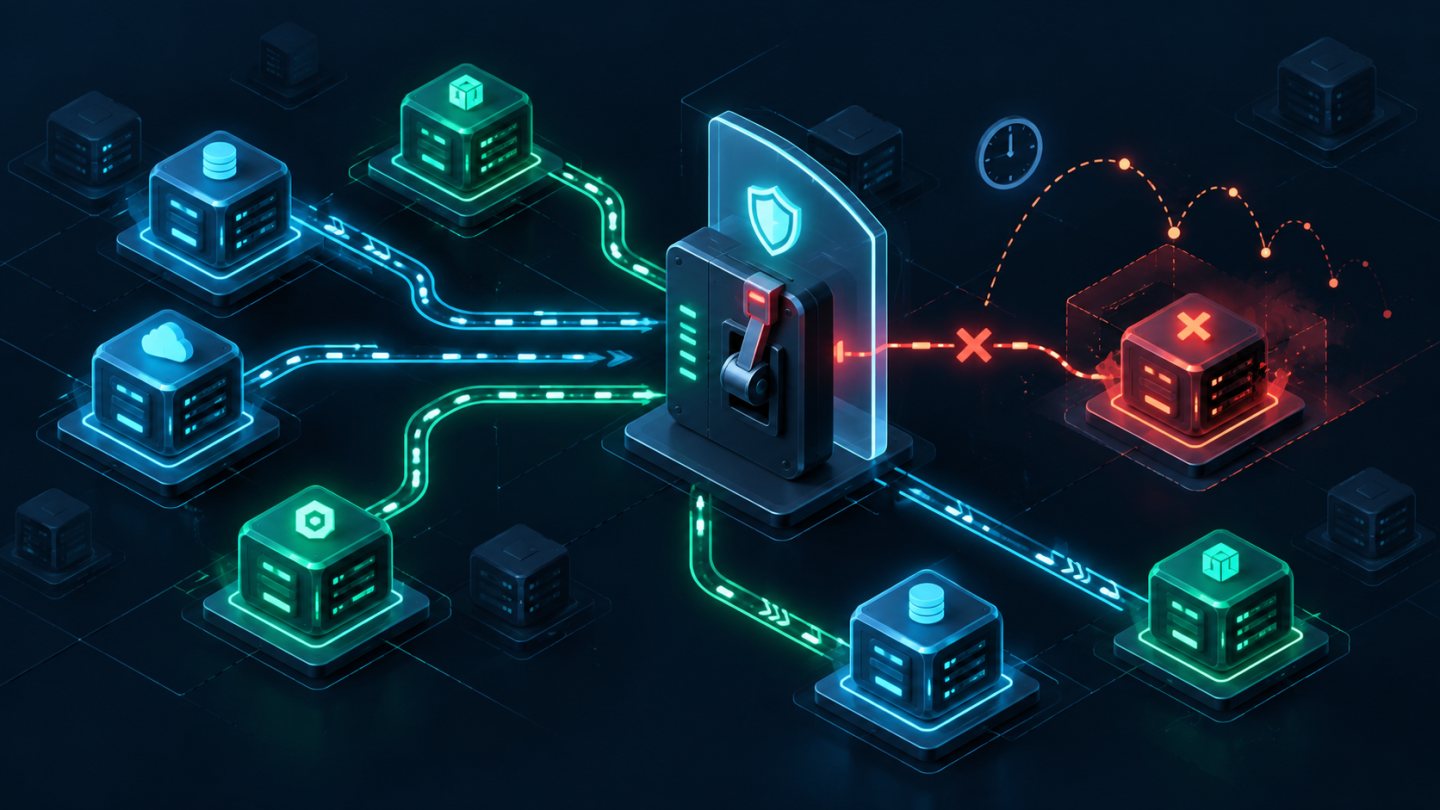
A slow dependency does not merely break one request. When every request holds a thread or connection and starts retrying, a small incident can become a system-wide cascading failure. Timeouts, retries, and circuit breakers address different parts of this problem: bounding wait time, repeating transient operations, and stopping calls to a dependency that is unlikely to succeed.
This guide builds a resilience policy from the request's time budget instead of copying arbitrary defaults. The examples use TypeScript-like pseudocode, but the principles apply to any backend platform and HTTP client.
Three mechanisms, three responsibilities
| Mechanism | Question it answers | Failure when misconfigured |
|---|---|---|
| Timeout | How long may one call wait? | Resources remain occupied, or valid calls are canceled too early |
| Retry | Which failures deserve another attempt, when, and how often? | Load is multiplied against an overloaded dependency |
| Circuit breaker | When should calls fail fast? | The circuit opens too eagerly or keeps hitting a broken service |
A retry assumes the failure may disappear soon. A circuit breaker assumes the dependency needs recovery time. They can work together, but an open circuit must stop further retries. A timeout is still required because the breaker only learns that an attempt failed after the client receives a result or reaches a deadline.
1. Start with an end-to-end deadline
Suppose an endpoint has an 800 ms response SLO. You cannot give all 800 ms to the payment service; authentication, database work, serialization, and returning the response need time too. Allocate the budget explicitly, perhaps 500 ms for the entire payment sequence and 180 ms for any one attempt.
request deadline: 800 ms
  local work:      180 ms
  payment budget:  500 ms (all attempts + backoff)
  safety margin:   120 ms
Separate connection and request/read timeouts where the client supports them. The overall deadline must include DNS, TCP/TLS setup, connection-pool waiting, body reads, retries, and backoff. Propagate the remaining deadline downstream so a service does not keep working after its caller has given up.
Derive values from real latency distributions by operation and region, not averages. Observe p95/p99, cold connections, and deployments. A timeout too close to p99 creates false timeouts during a mild latency shift; one that is too long can exhaust pools before the system recognizes an incident.
2. Retry only plausibly transient failures
Connection failures, timeouts, HTTP 429, and selected 5xx responses such as 502/503/504 can be candidates. Validation, authentication, authorization, and most other 4xx responses should not be retried. For 429 or 503, honor a valid Retry-After value when it still fits the deadline.
Data safety outranks success rate. GET is usually repeatable. A POST that creates an order or charges money should only be retried when the API supports an idempotency key or the business operation deduplicates requests. “The client did not receive a response” does not prove that the server did not commit.
function retryable(error, operation) {
  if (!operation.isIdempotent) return false;
  if (error.isNetworkFailure || error.isTimeout) return true;
  return [429, 502, 503, 504].includes(error.status);
}
3. Exponential backoff needs jitter and limits
If thousands of instances retry at exactly 100, 200, and 400 ms, they create synchronized load waves. Jitter spreads those attempts. A simple full-jitter formula samples between zero and a capped exponential delay:
cap = min(maxBackoff, base * 2 ** attempt)
delay = random(0, cap)
Always cap attempts, backoff, and the overall deadline. A retry budget also limits retry traffic across a client or service—for example, to a small fraction of original requests—so a broad outage cannot automatically double or triple load.
Do not retry at every layer. If the gateway, service A, and service B each make three attempts, one user request can generate dozens of downstream operations. Assign retry ownership to one layer, usually the caller that understands the operation and remaining deadline.
4. A circuit breaker is a state machine
- Closed: calls pass and the breaker records recent outcomes.
- Open: calls fail immediately or use a fallback without reaching the dependency.
- Half-open: only a small number of probes test whether recovery has occurred.
Do not trip on a single error. Practical policies use a minimum sample size, sliding window, failure or slow-call ratio, open duration, and half-open probe count. Keep separate breakers for independent endpoints or resources; one breaker spanning many shards or regions can block healthy capacity.
if (breaker.isOpen()) throw new DependencyUnavailable();

try {
  const result = await callWithTimeout(remainingDeadline());
  breaker.recordSuccess();
  return result;
} catch (error) {
  if (countsTowardBreaker(error)) breaker.recordFailure();
  throw error;
}
Count only failures that represent dependency health. A 400 caused by a bad payload should not trip the circuit; timeouts, connection failures, and 5xx responses are stronger signals. Limit half-open concurrency so the entire backlog does not flood a recovering service.
5. Compose policies around one shared budget
Wrapper order varies by library, but the semantics should be explicit: check the deadline and breaker before each call, apply a per-attempt timeout, retry only approved failures, never sleep beyond the remaining budget, and stop immediately when the circuit opens.
async function resilientCall(ctx, operation) {
  let lastError;
  for (let attempt = 0; attempt < MAX_ATTEMPTS; attempt++) {
    if (ctx.remainingMs() < MIN_ATTEMPT_MS) throw new DeadlineExceeded();
    if (!breaker.allowRequest()) throw new CircuitOpen();
    try {
      return await withTimeout(
        operation({ idempotencyKey: ctx.idempotencyKey }),
        Math.min(PER_ATTEMPT_MS, ctx.remainingMs())
      );
    } catch (error) {
      breaker.observe(error);
      lastError = error;
      if (!retryable(error, ctx) || attempt === MAX_ATTEMPTS - 1) throw error;
      const delay = retryAfter(error) ?? fullJitter(attempt);
      if (delay + MIN_ATTEMPT_MS >= ctx.remainingMs()) throw error;
      await sleep(delay);
    }
  }
  throw lastError;
}
In real code, timing out a promise may not cancel the socket or downstream work. Use the client's cancellation primitive, such as AbortSignal, and verify that connections are released. Fallbacks must also be bounded: stale cache, reduced data, or asynchronous queuing are useful options; calling another dependency in the same failure domain is not.
6. Observe before tuning
A minimum dashboard includes original requests, attempts, successful retries, exhausted retries, timeout phase, circuit state, rejected calls, half-open probes, per-attempt latency, and remaining deadline. Add dependency, operation, region, and outcome dimensions while avoiding high-cardinality labels such as user IDs.
Emit one structured event when the breaker changes state, including the cause and effective policy. Traces should show attempts as child spans, separating “slow downstream” from “slow because two backoffs occurred.” Alert on user impact and circuits that remain open, not on every individual retry.
7. Test failure modes, not only the happy path
- A dependency continuously returns 503: the circuit opens, downstream traffic falls, and callers fail fast.
- Latency exceeds the timeout: work is canceled, pools do not leak, and the overall deadline holds.
- A 429 includes
Retry-After: the client follows it only when it fits the deadline. - Half-open mode: only the configured probes pass; another failure returns the breaker to open.
- A POST response is lost after commit: an idempotency key prevents duplicate records or charges.
- Many instances fail together: jitter spreads retries and the retry budget prevents amplification.
Use fault injection in staging and load tests with changing error rates, latency, and packet loss. A good configuration is the one that satisfies your SLO with the dependency's actual behavior; version it, review it, and tune it from telemetry.
Production checklist
- Every remote call has a timeout inside an end-to-end deadline.
- Retryable failures are explicit, and mutations are idempotent.
- Backoff includes jitter, finite attempts, and a retry budget.
- The breaker has a minimum sample, sliding window, and bounded half-open concurrency.
- Fallbacks do not hide data errors or create another call loop.
- Metrics, structured logs, traces, and alerts have been verified with fault injection.
No comments yet. Be the first to share your thoughts.