
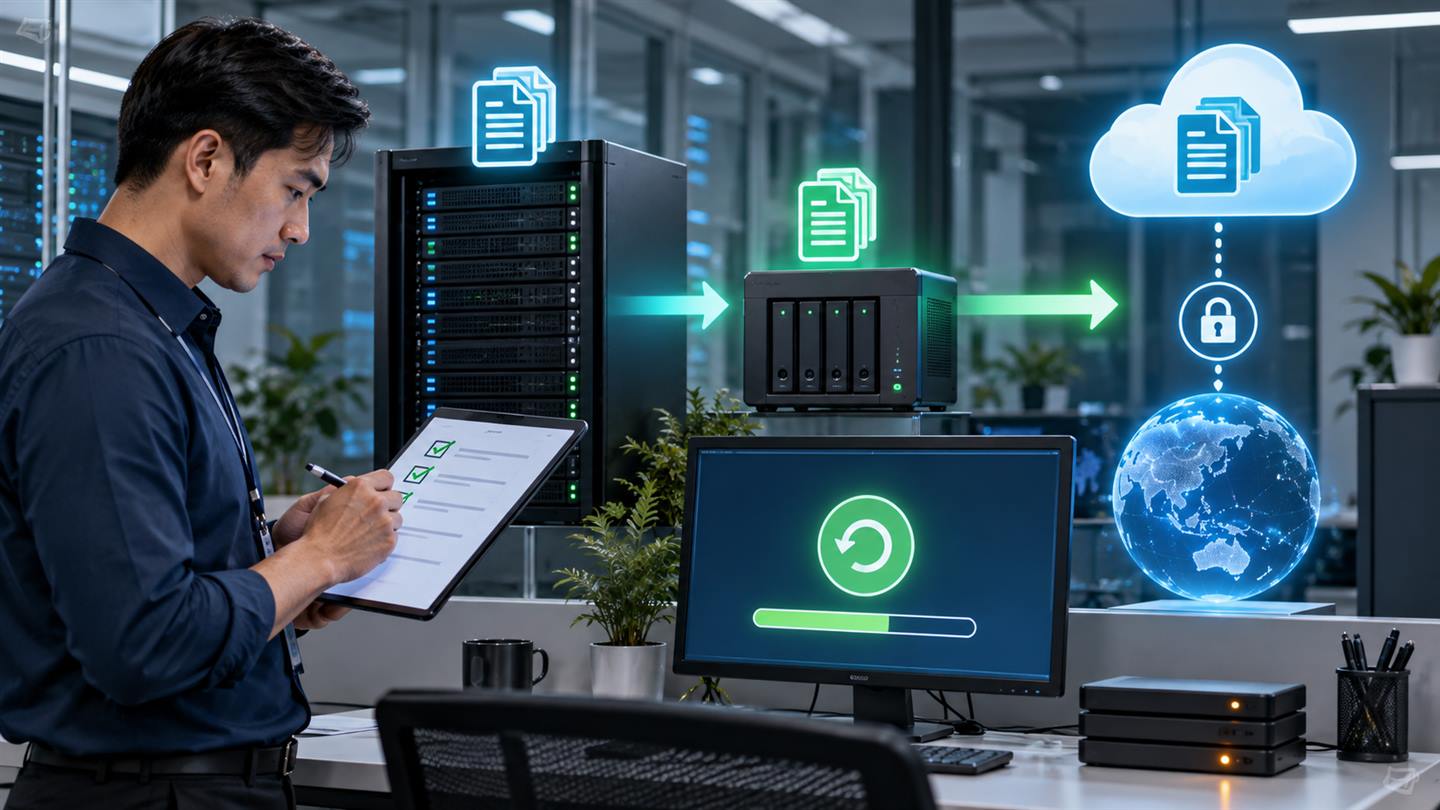
A backup is valuable only when it can restore the service. Copying a few files occasionally is not a recovery strategy. A reliable plan defines what is protected, how often copies are created, where they are stored, and how restoration is tested.
Step 1: Identify what must be backed up
- Application source and deployment configuration.
- Databases, uploaded media, and generated documents.
- Environment settings and infrastructure definitions.
- DNS, certificates, scheduled jobs, and integration configuration.
Secrets require special handling. Protect them with encryption and restricted access rather than placing unencrypted credentials in a general archive.
Step 2: Define RPO and RTO
Recovery Point Objective (RPO) is the maximum acceptable data loss measured in time. Recovery Time Objective (RTO) is the target time to restore service. A transactional website may need a much shorter RPO than a mostly static company website.
Step 3: Apply the 3-2-1 rule
- Keep at least three copies of important data.
- Store them on two different types of storage or independent systems.
- Keep at least one copy off-site or otherwise isolated.
For stronger ransomware protection, consider an immutable or offline copy that ordinary production credentials cannot delete.
Step 4: Choose schedules and retention
Combine frequent database backups with daily application and media backups. Use a retention policy such as daily, weekly, and monthly generations instead of keeping only the latest copy. Retention must also respect legal and privacy requirements.
Step 5: Automate and monitor
Automation reduces human error, but a successful command is not proof of a useful backup. Alert on missed schedules, unexpected archive size, checksum failure, storage capacity, and copies that have not reached the off-site destination.
Step 6: Encrypt and protect keys
Encrypt backups in transit and at rest. Store encryption keys separately, restrict deletion permissions, enable multifactor authentication, and audit access. Losing the only decryption key is another form of data loss.
Step 7: Test restoration
Run restore exercises in an isolated environment. Verify the database, uploaded files, application startup, user login, scheduled jobs, and external integrations. Record the actual recovery time and update the procedure after every exercise.
Scenarios to rehearse
- An accidental content deletion.
- A failed deployment or database migration.
- A compromised server or ransomware incident.
- A complete hosting-region outage.
- Loss of an administrator account or encryption key.
Handover checklist
- Owners and escalation contacts are documented.
- RPO and RTO are approved.
- At least one copy is isolated from production credentials.
- Monitoring sends actionable alerts.
- The latest restore test is recorded.
Conclusion
The 3-2-1 rule is a strong foundation, but operational discipline makes it effective. Treat restoration tests as part of normal website maintenance, not as an activity postponed until an incident occurs.
No comments yet. Be the first to share your thoughts.