
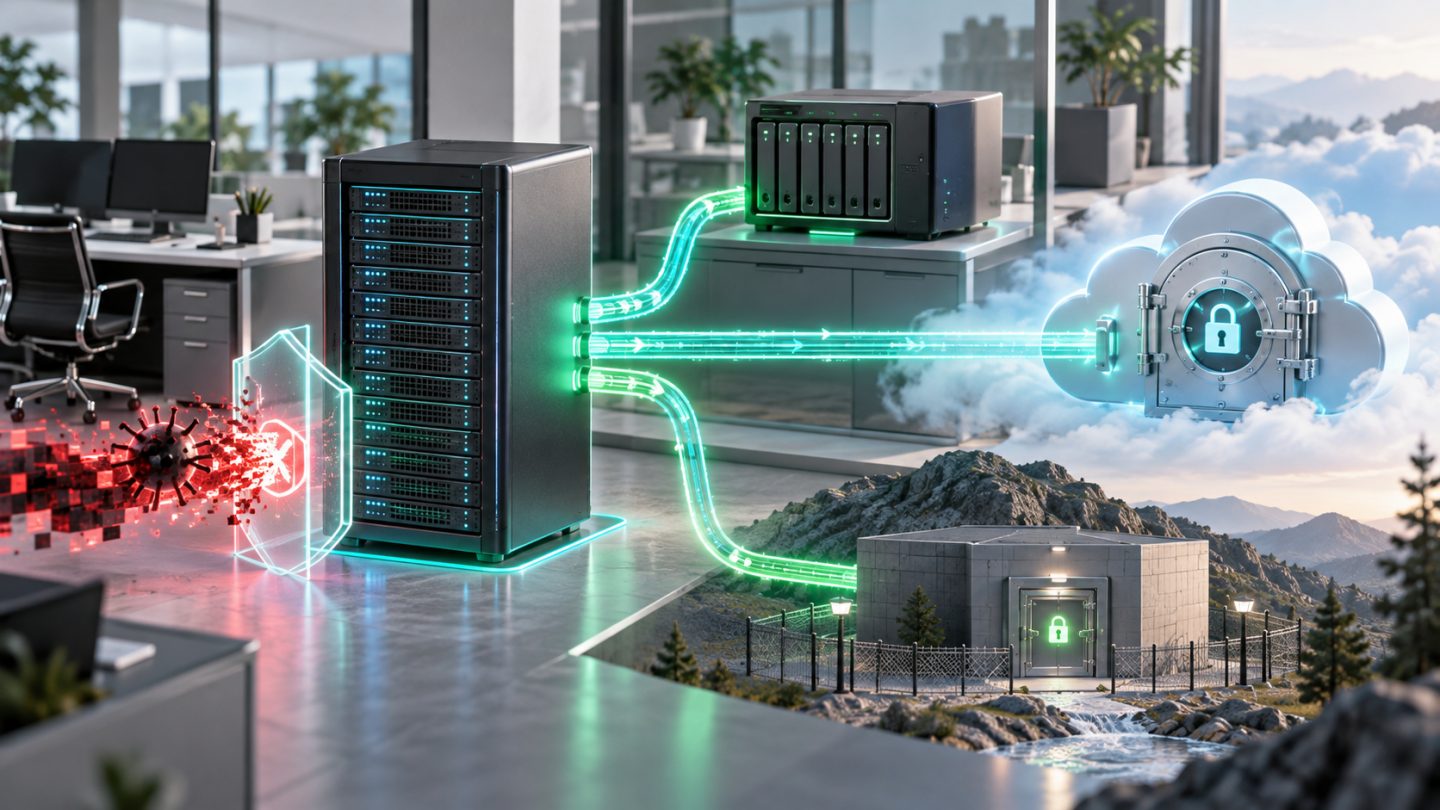
A copy on a NAS or in a cloud-sync folder is not a complete backup strategy. If an administrator account is compromised, ransomware may encrypt production data, delete snapshots, and destroy connected copies. The 3-2-1 model creates independent recovery layers so one incident cannot eliminate every way back.
What is the 3-2-1 backup rule?
- 3 copies of data: one production copy and at least two backups.
- 2 media types or platforms: for example, an office backup appliance and cloud object storage.
- 1 off-site copy: kept in an independent location or account so a local incident does not affect it.
For ransomware resilience, businesses often extend the idea to 3-2-1-1-0: add an offline or immutable copy and aim for zero errors after integrity checks. This is not a rigid formula. Its purpose is to remove shared failure points between production and recovery data.
Sync is not a replacement for backup
Synchronization makes new files quickly available on several devices, but deletions, encryption, and unwanted overwrites may also propagate. A real backup keeps versions under a separate retention policy and can restore data to a point before the incident.
| Tool | Primary purpose | Risk to manage |
|---|---|---|
| File sync | Convenient collaboration and access | Bad changes spread to synced copies |
| Snapshot | Fast rollback on the same system | Shared device or administrative domain |
| Backup | Recovery after deletion, failure, or attack | Requires monitoring, protection, and testing |
| Replication | Service continuity during infrastructure failure | Corrupted data may also be replicated |
Start with RPO and RTO
Recovery Point Objective (RPO) is the maximum acceptable data loss measured in time. If the order system has a 15-minute RPO, a nightly backup is insufficient. Recovery Time Objective (RTO) is the maximum time allowed to restore the service.
Not every system needs the highest tier. Transaction data may require a short RPO and recovery within hours, while a rarely changed archive may be backed up daily and restored more slowly. These decisions directly shape cost.
A reference architecture for a small business
- Production copy: active data on servers, endpoints, SaaS platforms, and databases.
- Local backup: a separate appliance or NAS using dedicated credentials and not mounted for every employee. This copy enables fast recovery.
- Off-site backup: cloud storage or another data center with encryption, versioning, and retention controls.
- Immutable or offline layer: object lock, an immutable vault, or removable media disconnected after backup.
If one provider hosts both production and backups, separate accounts, administrative roles, and credentials. For critical data, an independent administrative domain or provider can further reduce common risk.
Protect backups from the attacker
- Use dedicated backup accounts, MFA, and least-privilege access.
- Do not reuse domain administrator credentials for backup infrastructure.
- Enable immutability, delete protection, or object lock where available.
- Encrypt data in transit and at rest, and store recovery keys separately.
- Patch backup servers and restrict management interfaces from user networks.
- Alert on failed jobs, unusual storage growth, and bulk deletion requests.
Design schedules and retention
A simple schedule might include daily incremental, weekly full, and monthly recovery points. The actual schedule must follow the RPO, rate of data change, and the time ransomware could remain undetected.
Keeping versions across different time ranges reduces the chance that every recent backup already contains damaged data. Retention also needs a lawful deletion policy; personal data should not be stored forever merely because it might be useful someday.
Test recovery, not just backup jobs
A “successful” job does not prove that the business can recover. Quarterly, or according to system criticality, restore sample files, a database, and a virtual machine into an isolated environment. Measure real recovery time against the RTO.
- Confirm that files can be read and databases can start.
- Scan recovered data before returning it to production.
- Validate applications, permissions, and dependent systems.
- Document who can initiate a restore and who approves it.
- Update the runbook after every exercise or infrastructure change.
A 30-day implementation plan
| Stage | Actions |
|---|---|
| Days 1-7 | Inventory data, owners, and dependencies; define RPO, RTO, and recovery order |
| Days 8-14 | Configure local and off-site copies; separate administrative accounts |
| Days 15-21 | Enable encryption, MFA, immutability, alerts, and retention |
| Days 22-30 | Run a restore test, measure results, revise the runbook, and assign responsibilities |
Conclusion
3-2-1 backup is not simply a purchase of more storage. It is the design of independent copies, protected from shared credentials, followed by regular proof that recovery works. A modest system that is tested consistently is more valuable than an expensive platform that has never completed a recovery exercise.
No comments yet. Be the first to share your thoughts.